Is Local AI Worth It? I Did the Math for Creators
Microsoft's most expensive new laptop, the Surface Laptop Ultra, is due to ship on 16 October 2026. The version with 128 GB of memory costs $5,899, and Microsoft's US store reportedly sold out of it before a single one had shipped.
Other AI hardware has gone the same way. Nvidia's list price for an RTX 5090 graphics card is $1,999, yet the cheapest new one on sale on 11 October cost $4,921. The DGX Spark, Nvidia's small desktop box for AI, launched at $3,999 a year ago and now sells for about $6,950.
Every one of these machines is sold on local AI: models running on hardware you own, with no monthly fee, no usage caps, and your files staying where they are. My studio is small, and a MacBook Air already handles part of its pipeline, so I worked out what that promise is worth now that AI demand has pushed the hardware this high.
- Memory is why everything costs more. By the end of 2026, everyday computer memory is heading for five to six times its mid-2025 price, because AI chips take a growing share of the world's memory production.
- Local models read well and code badly. On a 128 GB machine, the strongest model available nearly matches Claude Opus 5.5 at answering questions about a long document, but scores 25% to Opus 5.5's 60% as a coding agent.
- Speed comes from memory bandwidth and software. The same 27-billion-parameter model writes 10 to 21 tokens a second on a 32 GB Mac mini and 51 to 59 on an RTX 5090 desktop.
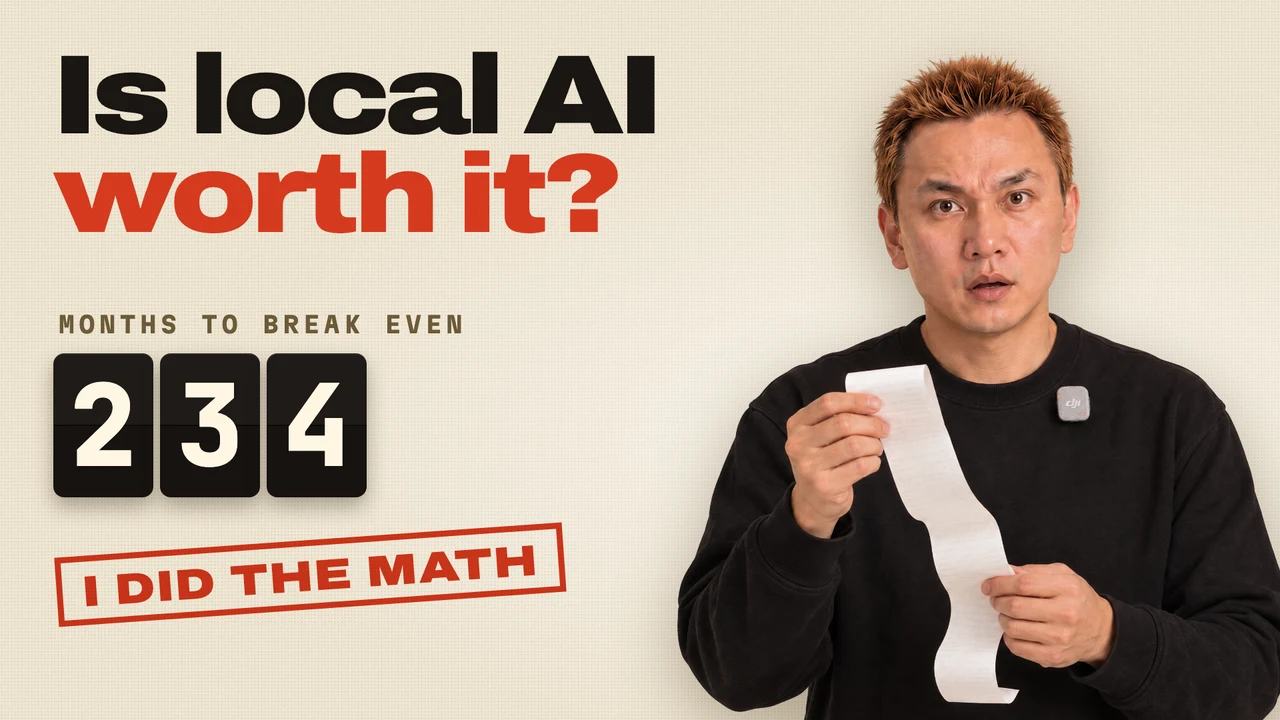
- A $5,000 box doesn't pay for itself on chat. Priced at what renting the same open model costs, a DGX Spark does about $21 of work in a working month, a 234-month payback.
- Local wins on private, repetitive jobs. My MacBook Air turns an 11-minute voiceover into text in 22 seconds, and nothing gets uploaded.
The video version. 10 min 6 sec. Watch on YouTube
- 0:00The $5,899 AI laptop that sold out
- 0:59Why RAM prices exploded
- 2:49How local AI works: the model has to fit
- 4:34One model, five machines: tokens per second
- 6:04Does a local AI box pay for itself?
- 7:38Local AI vs cloud AI: where local wins
- 9:34My verdict: own the chores
Why are computers so expensive in 2026?
Because of memory. Contract prices for ordinary computer memory (DRAM) are on track to reach five to six times their mid-2025 level by the end of 2026, going by TrendForce's quarterly figures, and anything with memory inside costs more as a result. Gartner put this spring's rise at about five times year on year, and OVH founder Octave Klaba says DDR5 costs six times what it did a year earlier.
AI is what's using up the supply. The chips in AI servers rely on high-bandwidth memory (HBM), built in stacked layers, which Micron says needs about three times the wafer area of ordinary DDR5 to store the same number of bits. Samsung puts HBM at about a fifth of the industry's DRAM wafer capacity now and nearly 30% next year. TrendForce projects that the nine largest cloud companies will spend about $957 billion on capital expenditure in 2026, more than double last year, and those buyers get served first.
The memory makers are booked up. Micron's revenue for its latest quarter was $54.2 billion, against about $11.3 billion a year earlier, and it says it has already committed more than 75% of its planned 2027 production. SK hynix's chief executive expects 2027 to be the worst year for supply in the industry's history.
Here's what that did to prices.
| Item | Before | Now |
|---|---|---|
| 32 GB DDR5 memory kit | $108 average, August 2025 | $572 average, August 2026 |
| Cheapest Mac mini | $599 (M4, 2024) | $899 (M6), after a rise to $799 in June 2026 |
| Mac Studio with Apple's Ultra chip | $3,999 (M3 Ultra, 2025) | $5,499 (M5 Ultra) |
| Framework Desktop, 128 GB | $1,999 at its 2025 launch | $3,449 |
| Nvidia RTX 5090 | $1,999 list price | $4,921, cheapest new on 11 October |
| Nvidia DGX Spark, 128 GB | $3,999 at launch, October 2025 | About $6,950 |
Apple raised Mac prices in June, and on its July earnings call Tim Cook described Apple's position on memory pricing as a 100-year flood. PlayStation and Xbox prices rose by $100 or more. Counterpoint's figures show the weakest July-to-September phone shipments since 2012.
How does local AI work?
Running AI locally means the whole model file sits in your computer's memory and your own chip writes the answers. If the model doesn't fit in memory, it won't run, so the amount of memory decides which models you can use at all.
A model is a large file of numbers called parameters. Compressed to 4-bit, the format most people run at home, it needs roughly half a gigabyte of memory per billion parameters. Qwen 3.8 27B, a popular open model, is 55 GB at full precision and 17 GB at 4-bit, and in Quesma's tests the compressed version performed about as well as the original.
Bigger open models use a design called mixture of experts. Qwen 3.8 Flash-Next has 125 billion parameters but only uses about 6 billion of them for each token it writes, which keeps it fast. All 125 billion still have to be stored, though, so it needs about 100 GB of memory at 4-bit. It's the model the 128 GB machines are bought for.
| Open model | Memory at 4-bit | Smallest machine that holds it |
|---|---|---|
| Qwen 3.8 27B | About 17 GB | 32 GB, such as a 32 GB Mac mini or an RTX 5090 |
| Qwen 3.8 Flash-Next (125B) | About 100 GB | 128 GB, such as a DGX Spark, a Strix Halo mini PC or a Mac Studio |
Tokens per second and time to first token
Two numbers decide how a local model feels to use. Tokens per second is how quickly the answer appears, and it mostly depends on memory bandwidth; a token is about three quarters of an English word. Time to first token is how long the machine spends reading your prompt before it writes anything, and that depends on raw computing power. Coding tools have a lot for it to read. Claude Code's own instructions run to about 33,000 tokens, roughly 25,000 words, on every request, so on home hardware the reading step often takes longer than the writing.
How good are local models?
| Model | Intelligence index | Long-document reading | Coding agent |
|---|---|---|---|
| Claude Opus 5.5 (cloud) | 58 | 85 | 60 |
| Qwen 3.8 Flash-Next (best for 128 GB) | 40 | 80 | 25 |
| Qwen 3.8 27B (best for 32 GB) | 34 | 82 | 6 |
Scores from Artificial Analysis in October 2026: its intelligence index, its long-context reading test (AA-LCR) and Terminal-Bench 4.0 for coding agents. Overall, the best models you can run at home trail the top cloud models by about three to six months. The gap depends on the job. When the task is answering questions about a long document, local models score close to Claude Opus 5.5. As coding agents, working on their own through many steps, they fall a long way behind. I'd give a local model the reading, summarising and tagging, and keep agentic coding in the cloud.
How fast is local AI? One model on five machines
Run the same model, Qwen 3.8 27B at 4-bit, and home machines write anywhere from about 10 to 59 tokens a second. Memory bandwidth explains most of the gap, and the software that runs the model explains much of the rest.
| Machine | Price, October 2026 | Tokens per second | Tested by |
|---|---|---|---|
| Mac mini M6, 32 GB | $1,299 | 10 to 21 | NightShift Tech |
| Nvidia DGX Spark, 128 GB | About $6,950 | 12 to 20 | Local Explained, Tom's Hardware |
| AMD Strix Halo mini PC, 128 GB | From about $3,100 | 12 to 33 | kyuz0 |
| Mac Studio M5 Ultra, 256 GB | From $5,499 (96 GB base) | 39 to 48 | MacStories, NetworkChuck |
| PC with an RTX 5090 | Card from $4,921 | 51 to 59 | MacStories |
Software explains a lot of the spread. NightShift Tech's Mac mini jumped from 9.6 tokens a second to 21 with nothing changed but the inference engine. Given the bigger Flash-Next model, the Mac Studio reached a median of 108 tokens a second in MacStories' test, because only 6 billion of its parameters do the work for each token.
At the far cheap end, Anthropic's red team spread a model across 15 TV boxes costing about $55 each. It ran at 0.39 tokens a second, a word roughly every 3 to 4 seconds.
The wait before the first word
Long prompts change the picture. NetworkChuck measured 21 seconds before the first token on the Mac Studio with a 32,000-token prompt. Local Explained works out that a DGX Spark needs 25 seconds to about a minute just to read Claude Code's 33,000-token prompt. One home user fed in a 50,000-token prompt and waited nine minutes.
Microsoft's new laptop is the unknown. When I ran these numbers in mid-October, nobody had tested the Surface Laptop Ultra independently, and the only speed figures came from Microsoft and Nvidia, measured on preproduction units. Judging by its memory bandwidth, I'd expect it to land closer to the DGX Spark than to an RTX 5090 desktop.
Does a local AI box pay for itself?
For chat and coding, no. Priced at what the same open model costs to rent, a $4,999 DGX Spark produces about $21 of work in a working month, which works out to a 234-month payback.
Most payback sums divide the price of the hardware by a subscription. The new 64 GB DGX Spark, on sale from 23 October at $4,999, set against a $200-a-month AI plan, gives 25 months. That compares the wrong things. A $200 plan buys you Claude Opus 5.5 or OpenAI's best model, and the box can run neither. It runs open models, and you can rent those exact models online for about $0.47 to $3.20 per million tokens.
Local Explained priced a DGX Spark's output that way. At 11.6 tokens a second for eight hours a day over 22 working days, the box produces about $21 of rentable work a month, so it takes about 234 months to pay back. Kai ran the same test on a $1,299 Mac mini. It pays back in 6.5 months on paper, but its actual output over a working month would cost about $15 to rent.
If you want to run your own numbers, these are the formulas:
- Napkin payback, in months = hardware price ÷ monthly plan price
- Honest payback, in months = (hardware price minus resale value) ÷ (the monthly cloud spend it actually replaces, minus electricity and upkeep)
- What the box produces each month = tokens per second × 3,600 × hours used × the rental price per token
Electricity hardly changes the answer. At the US average of 18.31 cents per kilowatt-hour, a Mac mini drawing 70 watts through a 176-hour working month costs about $2.26 to run, and an RTX 5090 desktop drawing 575 watts costs about $19.
Resale cuts the other way, for now. With memory this scarce, high-memory hardware holds its value. The three cheapest RTX 4090 listings on eBay averaged about $3,111 in October, nearly twice the card's $1,599 launch price. That only lasts while the shortage does.
Local AI vs cloud AI: where does local win?
Local wins on control, on client privacy and on fast creative chores. The cloud wins on the hardest thinking and coding.
Cloud plans change under you
The terms of cloud AI moved several times this year:
- In March, Anthropic changed Claude's limits so they drain more quickly during weekday peak hours.
- From 30 October, ChatGPT's $200 Pro plan comes with half its previous usage allowance.
- OpenAI closed the Sora video API on 24 September.
- On 1 December, the API price of Gemini 4 Argon, Google's flagship model, doubles.
- Apple has announced daily usage limits for its new Siri.
A model stored on your own disk only changes when you update it. Local apps can still switch to subscriptions, though. Topaz Video, an upscaler that runs on your machine, ended perpetual licences in October 2025. The same $299 that used to buy it outright now buys one year.
Client work and privacy
Google can keep Gemini chats that its human reviewers have looked at for as long as three years. In January, a US judge upheld an order for OpenAI to hand over 20 million ChatGPT logs, with personal details removed, as evidence in a copyright case. Netflix's guidance for production partners includes checking that AI tools won't store, reuse or train on production material. Material that never leaves your own drive avoids all of that.
Creative jobs run fast
| Job | Machine | Time |
|---|---|---|
| Transcribe a 2 h 5 min shoot (Whisper large-v3) | Mac Studio M5 Ultra | 90 seconds |
| Draft image (FLUX.2 klein 4B, 1024 × 1024) | Mac Studio M5 Ultra | 1.8 seconds |
| 4-second video clip with sound (LTX-2.5) | Mac Studio M5 Ultra | 17.8 seconds |
| Transcribe an 11 min 14 s voiceover (Whisper large-v3) | My MacBook Air M5, 24 GB | 65.2 seconds |
| The same voiceover with Whisper large-v3-turbo | My MacBook Air M5, 24 GB | 22.2 seconds |
The Mac Studio figures are NetworkChuck's. The MacBook Air runs are mine, from 14 October, on the voiceover of my last video, and I take my subtitle timings from those transcripts. The same laptop removes the background from photos of me for thumbnails and separates audio stems, and none of that client material gets uploaded anywhere.
Research and code stay in the cloud, where the best models are months ahead of anything I can run at home. A one-minute wait on every reply would cost me more in time than the subscription costs in money.
Where I land: own the chores
- Pay for one strong cloud plan and use it for research, writing help and coding.
- Put the private, repetitive work (transcription, footage tagging, cutouts, draft images) on hardware you already have.
- Don't buy a $5,000 box to cancel a $20 plan.
- If you need new hardware anyway, put the money into memory first. Micron expects supply in 2027 and 2028 to be even tighter than this year.
Before you buy anything, hand an old laptop one dull job this week and see how far it gets.
Frequently asked questions
Is local AI worth it?
For chat and coding, usually not. Priced at what the same open model costs to rent, a $4,999 DGX Spark produces about $21 of work in a working month, a 234-month payback. Local AI is worth it for private, repetitive jobs such as transcription, footage tagging and draft images, especially on a computer you already own.
How much memory do I need to run AI locally?
At 4-bit, a model needs roughly half a gigabyte of memory per billion parameters, plus room for your prompt. Qwen 3.8 27B needs about 17 GB, so 32 GB is a practical minimum for it. The 125-billion-parameter Qwen 3.8 Flash-Next needs about 100 GB, which is why people buy 128 GB machines.
Is local AI as good as ChatGPT or Claude?
Not overall. On Artificial Analysis's index, the best model a 128 GB machine can run scores 40 against 58 for Claude Opus 5.5, a gap of roughly three to six months. Local models come close at answering questions about long documents but fall far behind as coding agents.
Which is faster for local AI: DGX Spark, Mac Studio or RTX 5090?
On Qwen 3.8 27B at 4-bit, testers measured 51 to 59 tokens a second on an RTX 5090 desktop, 39 to 48 on a Mac Studio M5 Ultra and 12 to 20 on a DGX Spark. The DGX Spark and the Mac Studio have far more memory, so they can hold models that don't fit on a 32 GB RTX 5090.
Why is RAM so expensive in 2026?
AI chips use high-bandwidth memory, which needs roughly three times the wafer area per bit of ordinary DRAM, and it already uses about a fifth of the world's DRAM wafer capacity. With cloud companies buying first, everyday memory is heading for five to six times its mid-2025 price by the end of 2026.
What AI jobs can creators run locally?
Transcription and subtitles, footage tagging, background removal, upscaling, music stems, draft images and short draft video clips all run well on local hardware. A Mac Studio M5 Ultra transcribed a two-hour shoot in 90 seconds, and my MacBook Air transcribes an 11-minute voiceover in 22 seconds.
Sources
Prices and speeds were checked in mid-October 2026. Hardware prices are moving fast in the memory shortage, so check the date on anything you quote.
- Prices: Guru3D on the 128 GB Surface selling out, BuySellRam, RTX 5090 prices, ServeTheHome on DGX Spark prices, The Register on the 64 GB DGX Spark, 9to5Mac, M6 Mac mini, Engadget, Mac Studio M5 Ultra, Hardware Busters, Framework Desktop, TechTimes, DDR5 kit prices, PBS on Apple's price rises, Tim Cook's 100-year flood, 9to5Mac on Counterpoint's phone figures
- Memory: TrendForce DRAM contract prices, Gartner, OVHcloud, Samsung on HBM's share of wafers, TrendForce on cloud capex, Micron earnings call, Tom's Hardware on SK hynix's outlook
- Models and speeds: Quesma, Qwen 3.8 27B at 4-bit, Unsloth, Flash-Next memory, Artificial Analysis leaderboard, NightShift Tech, M6 Mac mini, kyuz0, Strix Halo benchmarks, MacStories, M5 Ultra Mac Studio, NetworkChuck's M5 Ultra data, Anthropic red team, TV boxes
- The math: Local Explained, DGX Spark payback, Kai, Mac mini payback, OpenRouter, Qwen 3.8 27B prices, EIA electricity prices, GPU Poet, RTX 4090 listings
- Where local wins: Claude's peak-hour limits, ChatGPT Pro usage halved, The Decoder on the Sora shutdown, Gemini API pricing, MacRumors on Siri's limits, Topaz pricing, Google on Gemini chat retention, ABA Journal on the 20 million logs, Netflix's AI guidance
Get the next post
New writing on AI and creative technology. No spam, unsubscribe anytime.
Delivered by Substack
Keep reading
Creative technologist and AI Forward Deployed Creative at Original Copy Studio.